You will need arrays, Java classes, and basic complexity analysis. Review Data Structures and Big O Notation if these are unfamiliar.
What are Hashtables?
A hash table is a data structure that stores associations between keys and values, then uses a key to find its associated value. A product code can identify a stock count, a customer ID can identify a customer record, and a word can identify how many times it has appeared. You ask for data by its key rather than by its position in a sequence.
This key-value association is called a map. For example, "tea" → 3 means that the value associated with the key "tea" is three. Each distinct key has one associated value: storing "tea" → 4 replaces the earlier value, while storing "coffee" → 2 creates a separate association.
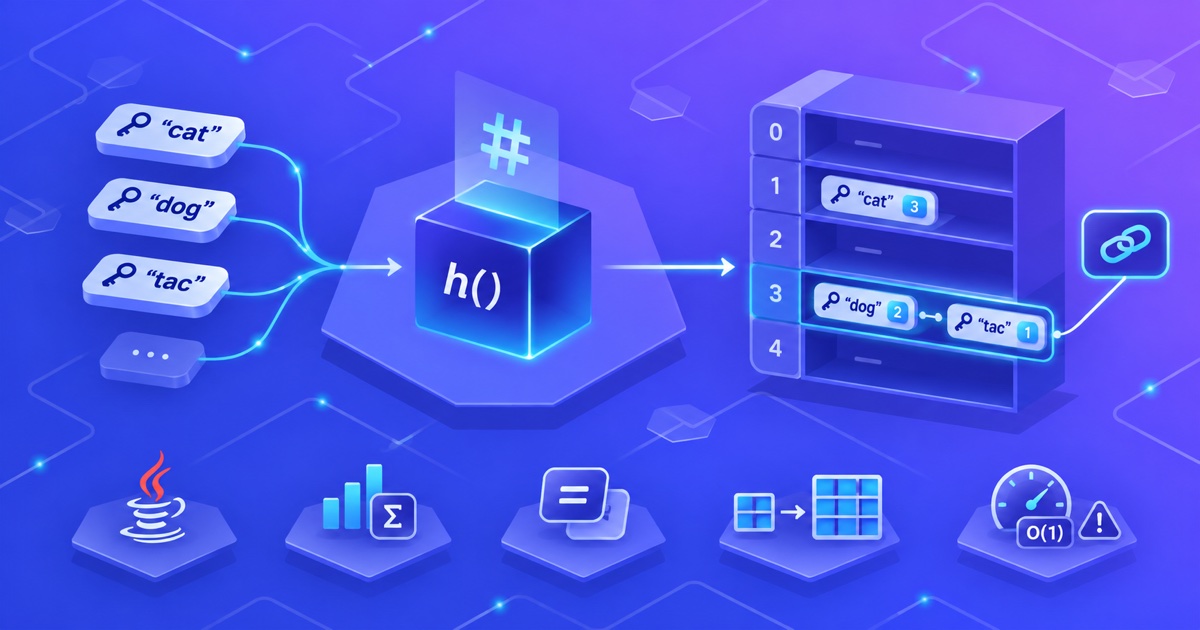
An array finds an element quickly when you know its index. A hash table makes use of that indexed storage by computing a likely location from the key. It then compares the keys stored there to find the exact association. Think of a cabinet with labeled compartments: a rule directs you to one compartment, and the labels distinguish the entries inside it.
The purpose is to avoid scanning every stored entry for each lookup. Hash tables are useful when repeated questions start with an exact key. Their defining ideas are key-based access, a hash function that directs that access, and a way to distinguish different keys that reach the same location. We will connect those ideas before using Java to build a frequency counter.
What are Hashtables characteristics?
Key-based operations
The main operations work on a mapping rather than a numerical position:
| Operation | Meaning | Example |
|---|---|---|
| Insert or update | Associate a key with a value | Store "tea" → 3, or replace its old count |
| Lookup | Retrieve the value associated with a key | Ask for the count of "tea" |
| Membership | Check whether a key is present | Ask whether "milk" has a mapping |
| Remove | Delete the association for a key | Remove the count for "coffee" |
An absent key needs an explicit result or policy, such as an empty result or a caller-provided default. Neither the order in which keys were inserted nor their alphabetical order determines these operations. Ordering guarantees depend on the implementation.
Hashing and buckets
A hash table implements that association using three connected ideas:
- A hash function turns a key into a number.
- An index calculation reduces that number to a valid position in a bucket array.
- A bucket stores the entries assigned to that position, retaining the original keys so the table can distinguish them.
Imagine a deliberately simple table with four buckets. For nonnegative integer keys, let the bucket index be key % 4.
| Key | Value | Bucket index |
|---|---|---|
| 10 | Tea | 2 |
| 14 | Coffee | 2 |
| 7 | Water | 3 |
Looking up key 14 selects bucket 2. The table checks the stored keys there, rejects 10, and returns Coffee for 14. It avoids examining bucket 3 or any empty bucket.
This modulo rule is a teaching model, not Java’s exact index calculation. A practical implementation also needs to distribute realistic keys well and handle the full range of hash values, including negative numbers.
Collisions and key equality
Keys 10 and 14 selected the same bucket. This is a collision. A finite bucket array cannot give every possible key a unique position, so collision handling is part of the design.
With separate chaining, a bucket holds a collection of entries, often illustrated as a linked list. A lookup checks candidate keys within that bucket. A collision adds another candidate; it does not overwrite an unrelated key’s value.
flowchart LR
    K["Lookup key 14"] -->|"14 modulo 4"| B["Bucket 2"]
    B -->|"First candidate"| A["Key 10: Tea"]
    A -->|"Different key; continue"| C["Key 14: Coffee"]
    C -->|"Equal key"| V["Return Coffee"]
Another approach, open addressing, stores entries directly in array slots and probes alternative slots when the first is occupied. Its deletion rules must preserve the probe sequence, commonly using a marker for a deleted slot. Both approaches retain enough information to tell an equal key from a collision.
The important distinction is between locating candidates and proving equality. A matching bucket narrows the search; comparing keys decides whether you found the requested mapping.
Load factor and resizing
As entries accumulate, more candidates can collect in each bucket. The load factor is the ratio of stored entries to buckets. In our four-bucket teaching model, three entries give a load factor of 3 / 4 = 0.75.
A table can grow its bucket array and redistribute entries using the new capacity. For example, if we change our teaching model from four buckets to eight, key 10 selects bucket 2, while key 14 selects bucket 6. They no longer collide. Keys with identical hash values can still collide after growth; resizing cannot repair a hash function that sends everything to the same place.
Java’s HashMap uses a default load-factor threshold of 0.75 and grows when its entry count exceeds the capacity multiplied by that threshold. Growth trades additional space and occasional rebuilding work for shorter bucket searches. It also provides no iteration-order guarantee and is not synchronized. These behaviors are documented in the HashMap API.
Time and space costs
Let n be the number of mappings and m the bucket capacity. With well-distributed hashes and bounded load, a lookup examines a small expected number of candidates. This gives expected O(1) lookup, assuming computing a hash and comparing keys are themselves constant-cost operations.
| Operation in a conventional chained hash table | Expected cost under those assumptions | Important exception |
|---|---|---|
| Find or remove a key | O(1) | A long collision chain can require O(n) comparisons |
| Insert or replace | Amortized O(1) | An insertion that grows the table can take O(n) |
| Visit every entry | O(n + m) | Empty buckets still contribute to an array scan |
Expected describes the effect of hash distribution. Amortized spreads occasional resizing work over many insertions. They answer different questions: good distribution does not prevent one insertion from triggering a resize.
These bounds describe the conventional chained model, rather than a promise about every library implementation. Implementations may add collision defenses, but you should still avoid assuming that every individual map operation has constant latency. Long string keys can also make hashing or equality work significant.
Hashtables in action - code examples
The general rules now translate into two Java responsibilities: choose keys with consistent equality, then use map operations to store and retrieve values. HashMap is the hash-table implementation used below.
Choose safe Java keys
In Java, hashCode() supplies the hash value and equals() defines logical equality. Equal objects must produce equal hash codes, while unequal objects may share one. A class that defines value equality should implement both methods consistently. These are requirements of the Object contract.
Suppose two separately created customer objects both represent customer ID 42. If ID defines equality, both objects must hash consistently so a lookup using one can find a mapping inserted with the other. If you compare IDs in equals() but inherit identity-based hashing, the lookup may search elsewhere.
Immutable strings are convenient keys because their equality and hashing already follow this contract. For a custom key, base both methods on the same stable identity fields. A Java record can help express such a value, but its components also need appropriate equality behavior and should remain stable.
Do not change fields involved in a key’s equality or hashing while that key is stored in a hash map. A later lookup can select a different bucket and fail to find the existing entry. Prefer immutable keys, or remove the entry before changing its identity and insert it again afterward.
Build a frequency counter
We will count the words tea, coffee, tea, and water. The map starts empty. For each word, we retrieve its previous count, using zero when the key is absent, then store the count plus one.
Map<String, Integer> describes string keys and integer values. HashMap supplies the implementation. getOrDefault(word, 0) makes the missing-key case explicit; Java converts between primitive int values and their Integer wrappers as needed.
Save this complete example as WordCounts.java. It uses only standard Java library classes.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
import java.util.HashMap;
import java.util.Map;

public class WordCounts {
    public static void main(String[] args) {
        String[] words = {"tea", "coffee", "tea", "water"};
        Map<String, Integer> counts = new HashMap<>();

        for (String word : words) {
            int previous = counts.getOrDefault(word, 0);
            counts.put(word, previous + 1);
            System.out.println(word + ": " + previous + " -> "
                    + counts.get(word));
        }

        // Explicit lookups keep the output independent of map iteration order.
        System.out.println("tea count: " + counts.get("tea"));
        System.out.println("distinct words: " + counts.size());
        System.out.println("milk present: " + counts.containsKey("milk"));
        counts.remove("coffee");
        System.out.println("coffee after removal: "
                + counts.getOrDefault("coffee", 0));
    }
}
Run it with javac WordCounts.java followed by java WordCounts:
1
2
3
4
5
6
7
8
tea: 0 -> 1
coffee: 0 -> 1
tea: 1 -> 2
water: 0 -> 1
tea count: 2
distinct words: 3
milk present: false
coffee after removal: 0
On the first tea, the lookup finds no equal key, so we store 1. On the second tea, it locates the existing mapping and replaces 1 with 2; the number of distinct keys stays unchanged. coffee and water add separate mappings. Their bucket placement is an internal detail: even if they collide, key comparison keeps their counts separate.
Removing coffee deletes that mapping. The final default value is returned by the lookup; it does not insert coffee again. Notice that counting needs key lookup, not sorted order or positional access.
For our counter, let N be the number of input words and D the number of distinct words. Under the same assumptions, processing takes expected amortized O(N) time and O(D) additional storage. A growing number of repeated words adds processing work without adding a mapping for every repetition.
What problems can Hashtables solve?
A hash table fits exact-key lookups, grouping, deduplication, and frequency counting. Use a hash set when you only need membership rather than associated values.
If you need keys in sorted order, predecessor queries, or range queries, consider an ordered tree structure. If small integer keys already correspond to a compact index range, a plain array can be simpler and use less overhead. If you need insertion-order traversal in Java, LinkedHashMap expresses that requirement explicitly.
For example, a stock service can retrieve the quantity for a product code, a log analyzer can group records by user ID, and an import routine can remember identifiers already processed. Each task repeatedly starts with a key. The frequency counter demonstrates the same access pattern on a small input: the current word tells us which count to read and update.
Conclusion
Hash tables organize key-value mappings around a computed storage location. Hashing narrows the candidates, equality identifies the requested key, and collision handling allows different keys to share a bucket without losing their mappings. Resizing controls the load as the collection grows.
Their expected constant-time operations depend on well-distributed hashes, controlled load, and the cost of hashing and comparing keys. Choose stable keys and make the absent-key case explicit. When the workload needs repeated exact-key access, these choices let the table replace a full scan with a much smaller search.